


IT portfolio management earns its place when a review ends with an operating decision. The team can see what is running, which service depends on it, who owns it, what it costs, and whether it should stay.
In a multi-cloud estate, those answers sit in different systems. Cloud APIs provide the cloud inventory. Billing exports know the spend. Infrastructure-as-code repositories show intended state. CMDB records carry ownership and relationships, provided the records stay current.
This guide shows how to turn that scattered evidence into a working IT portfolio. It covers the live technology estate, from applications and infrastructure to lifecycle status, cost, and risk. Project portfolio management appears only where a project hands a new or changed service into operations.
What is IT portfolio management?
IT portfolio management, or ITPM, keeps technology investments and the systems they create ready for review. Each application, service, platform, or infrastructure component should carry the context needed for a decision, including owner, business purpose, cost, lifecycle state, dependencies, and risk.
The test is simple. An inventory tells you what exists. A portfolio shows what to fund, fix, consolidate, replace, or retire.
The scope varies by organization. Some teams manage proposed investments and active projects inside the same portfolio. Others separate project demand from the operating estate. This guide concentrates on the second view because cloud resources change long after the project that introduced them has closed.
The minimum record behind a portfolio decision
| Field | What the reviewer needs to know | Typical evidence |
|---|---|---|
| Identity | What the item is and where it runs | Provider resource ID, account, region, CMDB class |
| Business context | Which service it supports and who is accountable | Service relationship, owner, business unit, criticality |
| Financial context | What it costs and how spend is allocated | Billing data, cost center, contract or license record |
| Control state | Whether exposure and policy status are acceptable | Security findings, compliance controls, exceptions |
| Lifecycle | Whether to invest, maintain, migrate, consolidate, or retire | Observed activity, roadmap, change history, approved decision |
IT portfolio management versus project portfolio management
| Dimension | IT portfolio management | Project portfolio management |
|---|---|---|
| Primary unit | Applications, services, platforms, infrastructure, contracts, and IT investments | Projects and programs |
| Decision | Invest, maintain, migrate, consolidate, replace, or retire | Start, pause, resequence, resource, or stop |
| Time horizon | Continuous, through the operating lifecycle | From proposal through project closure |
| Evidence | CMDB, enterprise architecture, billing, security, asset, service, and vendor data | Business cases, roadmaps, schedules, budgets, dependencies, and capacity plans |
| Handoff | Receives the service and its operating obligations | Delivers the approved change |
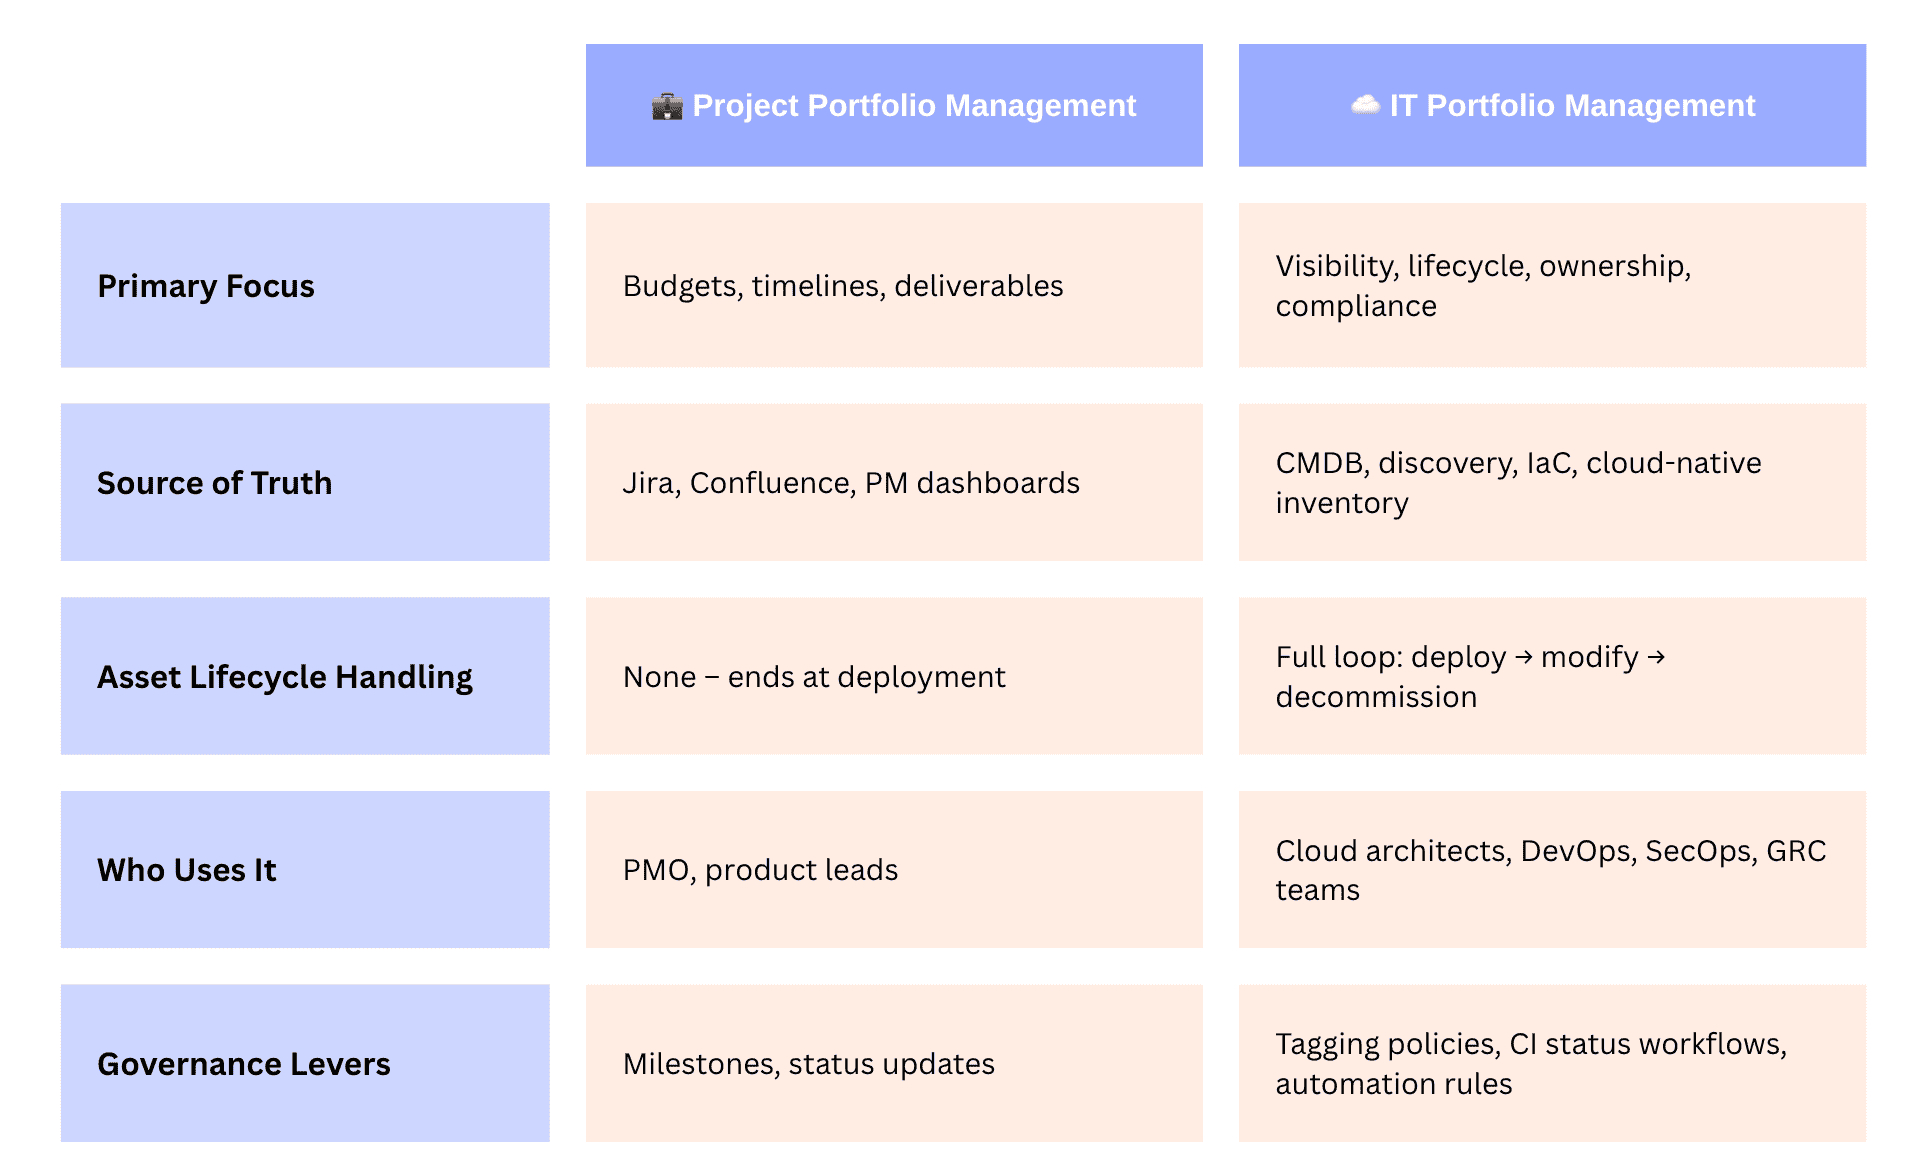
When a migration project ships, the service and infrastructure it introduced enter the operating portfolio. They still need an accountable owner, lifecycle state, cost allocation, dependency context, and a review date.
What a working IT portfolio lets teams decide
A working IT portfolio earns its keep in review meetings. It shortens the path from a cloud resource or application record to a defensible decision. The five views below show what teams can decide with that evidence.
1. Which systems exist and how they connect
Visibility becomes useful when a CI can be traced to its parent service, environment, accountable team, and source. Native cloud inventory, CMDB relationships, tags, and infrastructure-as-code metadata may contribute different parts of that record. Missing fields should remain visible as data-quality gaps so reviewers can address them.
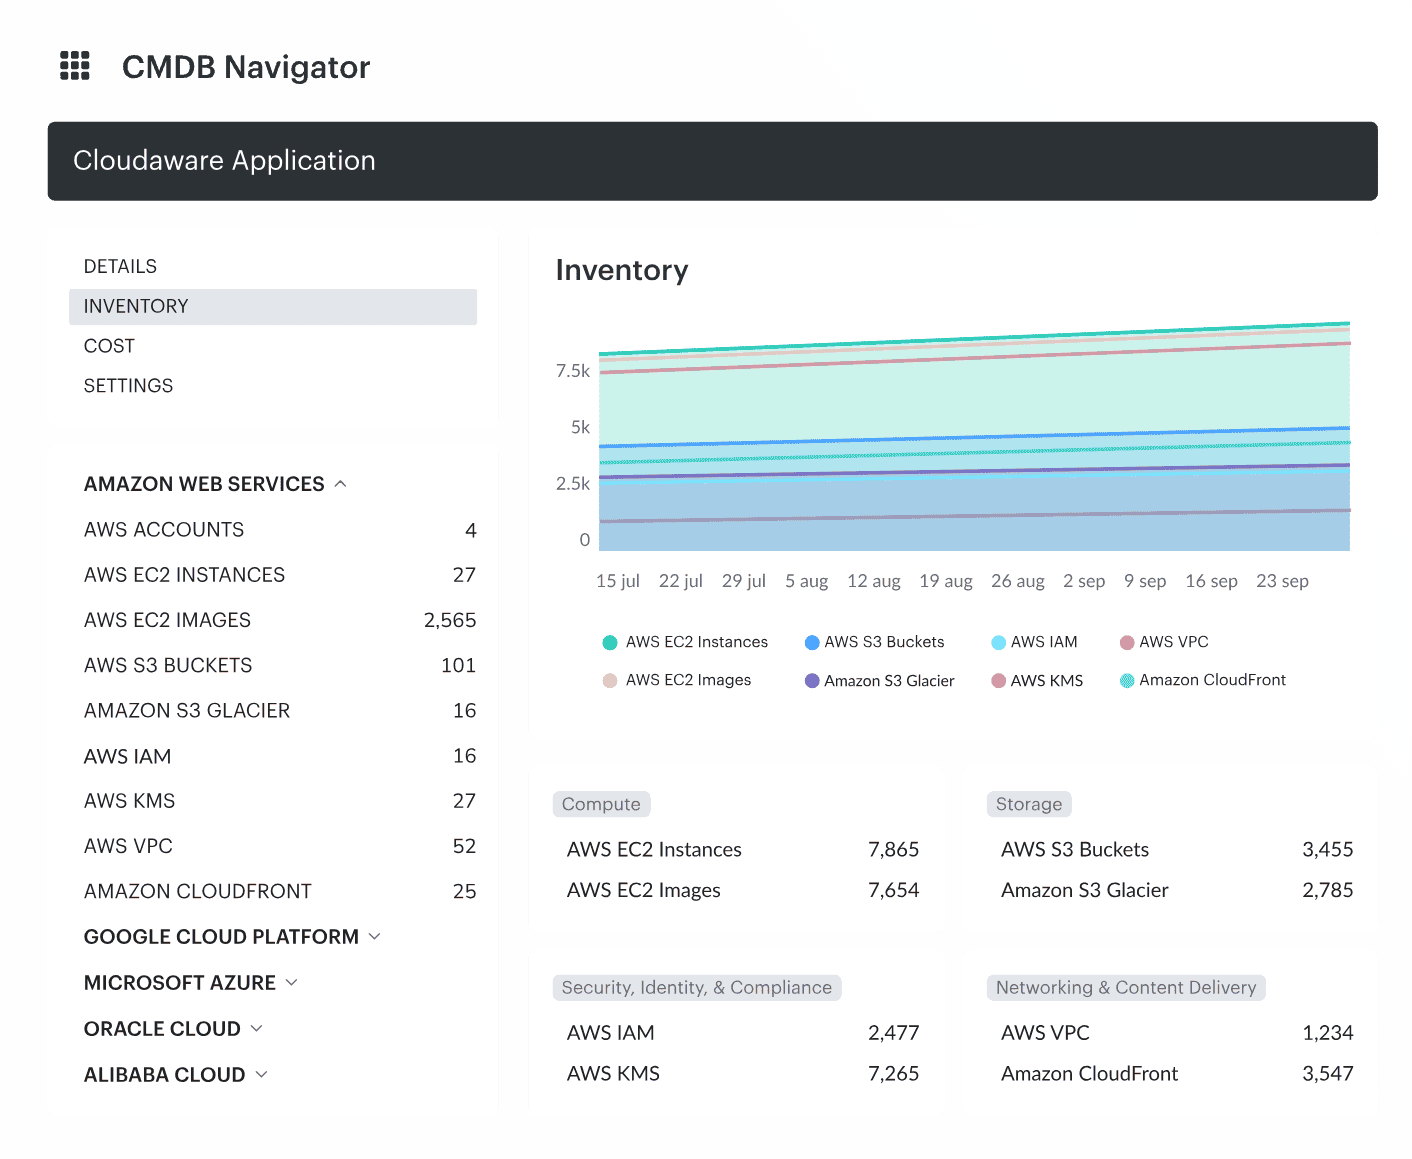
Element of the Cloudaware inventory dashboard.
For example, an EC2 instance may relate to an Auto Scaling group, an application tier, and a business service. Operations, security, and FinOps can then judge whether a finding, cost anomaly, or lifecycle event requires action.
2. Where spend has no owner or business purpose
Cloud waste is brutal when you can’t see what’s idle.
ITPM lets you tie usage and lifecycle status together. An asset marked “Retire Pending” can enter a decommission review when a workflow is configured. Use usage and storage data to identify orphaned volumes, then verify dependencies and retention requirements before moving or retiring them. Cloud cost allocation connects charges to cost centers and owners where billing data and mapping rules support it.
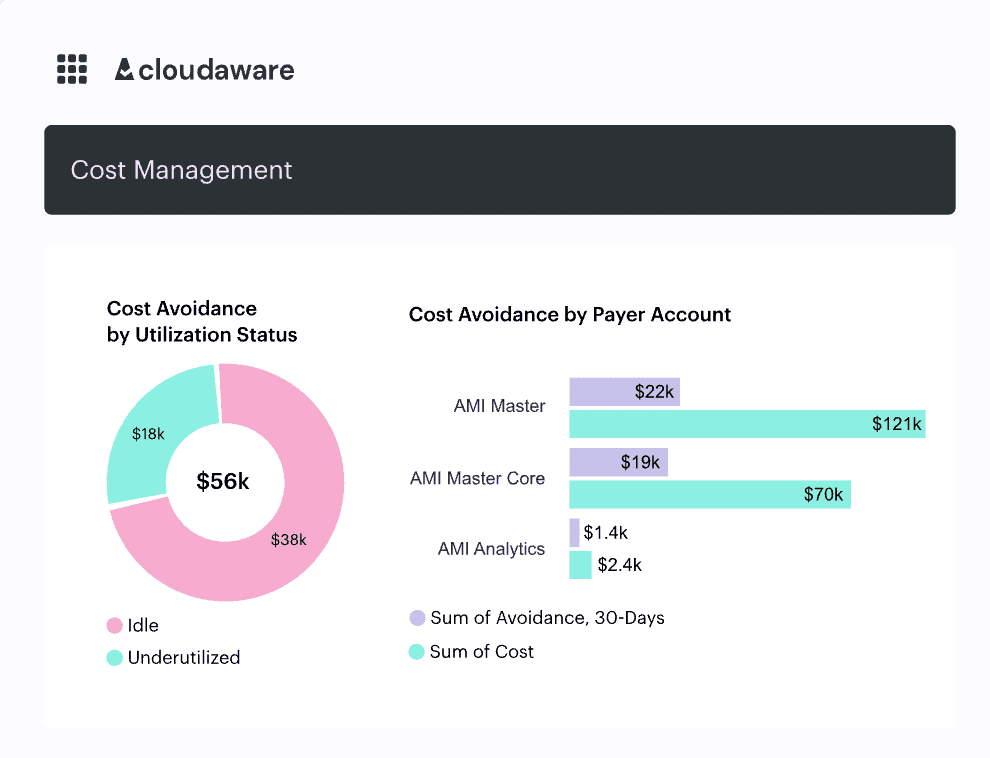
Element of the Cloudaware FinOps dashboard.
Configured cleanup policies and cloud budgets can flag temporary environments or spending that need review.
Suddenly, your monthly report isn’t “where did this bill come from?” It’s “here’s where we saved, here’s who needs to optimize.”
3. Which policy failures need action
Tag enforcement can run during deployment to check for a named owner. A separate policy can check whether an S3 bucket is publicly accessible.
Discovery can surface missing tags. Configured policy checks can flag a lifecycle change or a violation of a data residency or encryption rule.
A CMDB record can give the receiving team the resource and ownership context. Configured integrations can route findings into tools such as Jira, ServiceNow, or Slack.
4. Which lifecycle changes are stale
Think about your “Modify” state. How many assets are stuck there because no one updated the record?
Use asset lifecycle management to define the evidence and rules behind state changes. A team might configure these review signals.
- A provider termination event flags a CI for retirement review.
- A CI with missing tags is flagged when it exceeds the evidence window for its class.
- A deployment approval prompts the owner to confirm the production state.
Cloud events, IaC pipelines, and GitOps metadata can provide the signals. The team defines which signals warrant a status change and which require approval.
5. Which services support each business outcome
A configured application or service map can bring together the fields needed for an alignment review.
- CI relationships by service
- Ownership by team
- Compliance by status
- Cost by project or initiative
When the CIO asks “what infra supports this customer-facing app?” — you don’t build a slide.
You send a live link.
That’s what ITPM does. It connects the cloud you built to the business you serve. The view reflects the records and relationships available at review time.
This isn’t a wishlist. It’s what modern ITPM looks like when your tools stop treating ops like a black box.
When the portfolio has stopped being decision-ready
Repeated decisions that stall because of missing evidence are a sign that the portfolio needs attention. The size of the estate alone tells you little.
Use the signals below as a diagnostic. Measure the baseline first. Then set thresholds that fit the change rate and risk of your environment.
| Signal | Evidence to inspect | Decision being blocked |
|---|---|---|
| Ownership gaps recur | Resources or services with no accountable team, stale directory mapping, free-text owner tags | Who approves remediation, spend, or retirement |
| Services cannot be reconstructed | CIs with no application or service relationship, conflicting service maps | What a change or incident can affect |
| Spend is not allocable | Charges without cost center, product, environment, or owner context | Where to optimize and who owns the outcome |
| Lifecycle states disagree | Terminated resources marked active, active services marked retired, records with no observed change | What to keep, migrate, or retire |
| Audit evidence is assembled manually | Repeated exports, screenshots, and ad hoc reconciliation across tools | Whether controls operated during the required period |
| A migration or reorganization changes ownership | New accounts, teams, platforms, vendors, or service boundaries | How the portfolio should be reclassified |
Do not wait for every signal to appear. Pick one decision with a visible owner and a bounded scope, such as production cloud resources for one service. Reconcile the evidence, record the exceptions, and test whether the review now ends with an action. That is a better pilot than loading every asset into a new dashboard.
These gaps also affect day-to-day IT asset management, especially when the same missing evidence blocks an audit or change review.
Inventory & categorize
Start by reconciling evidence from provider APIs, on-prem discovery, infrastructure-as-code, identity and ownership data, billing records, and security controls.
Keep observed state separate from intended state. A cloud API can confirm that a resource exists. Terraform can show how the resource was meant to be configured. A tag may suggest an owner, but an approved directory mapping or service record may carry more authority. When sources conflict, preserve the conflict and route it for review.
Normalize identity before classification. Resolve the provider resource ID, account or subscription, region, and resource type to one CI. Only then add service, owner, cost center, lifecycle, and risk context. Otherwise, a polished portfolio can still contain duplicates.
Cloudaware can provide the CMDB layer for querying multi-cloud and on-prem inventory, relationships, ownership, cost, and change context. The implementation still needs precedence rules for each field and a workflow for unresolved records.
Use these candidate sources when building each CI record.
- Observed inventory can come from provider sources such as AWS Config, Azure Resource Graph, and GCP Asset Inventory.
- CI type can come from normalized resource types such as
EC2,S3,AKS,SQL MI,Cloud Function,Firewall, andIAM Group. - Context fields depend on the sources and mappings available for each CI.
- Environment can come from tags and deployment metadata.
- Lifecycle phase (for example,
Provisioned,Operational, orRetire Pending) needs observed activity and the team’s state rules. - Business service can come from dependency relationships and configured service mapping.
- Owner can come from approved directory or service mappings, with IaC annotations and repository maintainers as candidate signals.
- Cost center, region, project association, and deployment source can come from billing records, provider metadata, and deployment records.
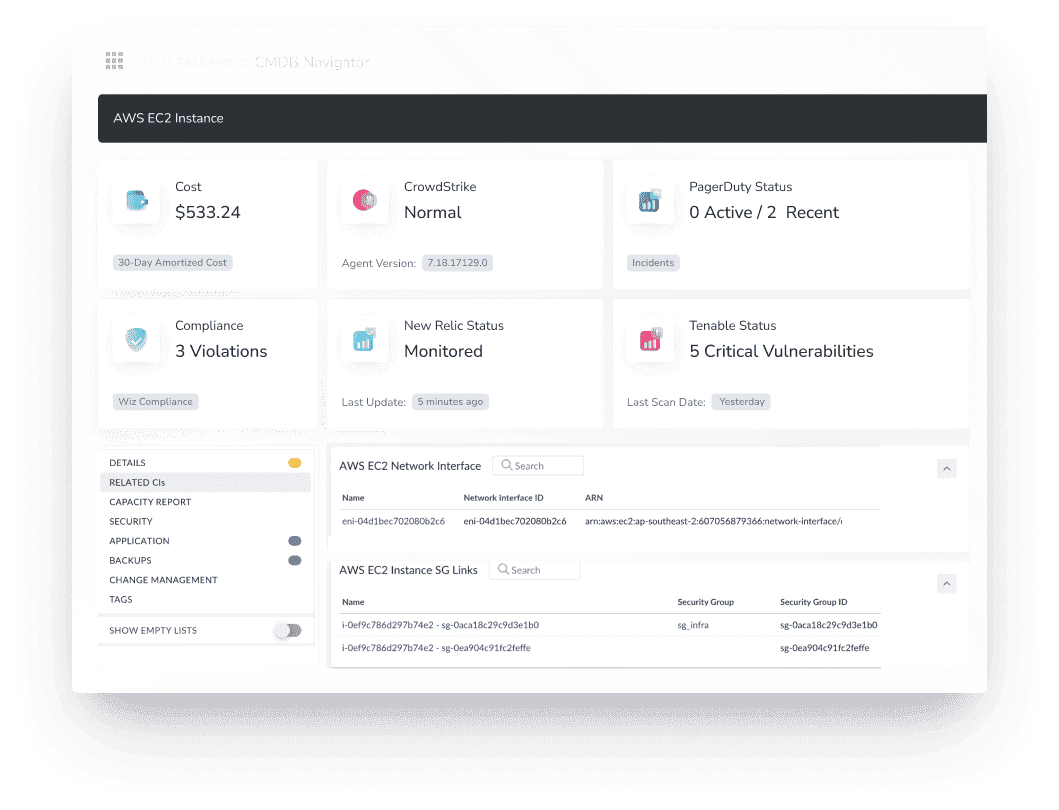
This wasn’t just a cleanup. It was portfolio alignment in real-time.
Because the minute you can group resources by business purpose, cost accountability, and lifecycle phase — you’re not just doing infra ops. You’re enabling strategic portfolio management at the architecture level.
That’s what organizations actually need from IT. Not “how many EC2s do we have,” but “what’s powering this app, who owns it, and is it still needed?”
Inventory & Categorize step isn’t glamorous. But it’s the foundation. Nail it, and you’ll finally have a CMDB that reflects the real state of your infrastructure — not just what was deployed last quarter.
Read also: Everything you should know about IT hardware asset management in 2025
Align with strategy
Once your inventory’s clean — your IT assets are discovered, categorized, and tagged — step two in the IT portfolio management journey is all about alignment.
And not just alignment for the sake of a slide deck.
I’m talking real-world, architectural-level portfolio alignment with the business objectives your company actually cares about.
Because here’s the pattern I see too often: Infra is humming, CIs are deployed, engineers are moving fast — but no one can trace which projects, applications, or services actually map back to strategic goals.
So here’s where we shift. We go from “what do we have?” to “why do we have it — and what is it helping us achieve?”
In Cloudaware CMDB, we start by anchoring to business initiatives. Usually, these come from enterprise architecture teams, the CIO roadmap, or the project portfolio management office.
Think:
- “Improve customer retention through digital experience”
- “Reduce cloud cost by 20% this fiscal year”
- “Replatform legacy workloads to Kubernetes”
- “Ensure regulatory compliance for all external-facing systems”
Next, we map resources — VMs, containers, load balancers, secrets, storage buckets — to these business objectives.
We build relationships across the stack: CI → Application → Business Service → Initiative
We tag with project codes.
We layer in cost centers.
We align compliance and risk data across the portfolio.
And we let the CMDB become the single source of truth not just for infra — but for how that infra powers the business.
The result? You stop thinking in assets. You start thinking in value streams.
Now every engineer, architect, or security lead can answer:
- “Which projects are these assets tied to?”
- “What strategic outcome is this cluster supporting?”
- “Why are we still funding this service if the initiative closed last quarter?”
That’s what portfolio management looks like when it’s connected. And when organizations reach that point, they stop reacting to infra, they start using it to drive the company’s next move.
Once you've aligned your infrastructure with actual business objectives, the next step in the IT portfolio management strategy is where things get spicy 😈
Optimize & rationalize
This step is about assessing your current resources — apps, services, infrastructure — and deciding what to consolidate, what to replatform, and what to decommission.
Here’s how we do it with enterprise clients using the CMDB:
1️⃣ Group CIs using virtual applications, environment tags, and initiative metadata
Start by organizing your infrastructure using Virtual Applications. These groupings let you cluster CIs based on app boundaries, platform teams, or product domains — even if the assets span multiple cloud providers.
→ Use environment tags (dev, stage, prod) pulled from discovery and IaC metadata.
→ Leverage custom fields or label policies to assign initiative names, project codes, or internal tracking IDs.
→ Identify stray CIs not tied to any Virtual Application or initiative — these often signal technical debt or legacy drift.
This gives your IT portfolio structure: defined service boundaries, environment visibility, and a baseline for business alignment.
2️⃣ Enrich CIs with operational & lifecycle data
Enrich each CI with the fields required by the next decision. Discovery contributes observed configuration. Billing data contributes cost. Tags, infrastructure-as-code, identity systems, and service maps add context. Define which source takes precedence for each field. Record where each field came from and when it was last confirmed.
3️⃣ Apply rationalization logic based on real conditions
Use review rules to surface candidates. A useful rule set can flag the following conditions.
- A CI with no accountable owner or service relationship
- A terminated resource whose portfolio record still says operational
- Persistent spend after an environment or initiative has closed
- Two services that appear to provide the same capability
- A production resource with an exposure or policy exception and no approved owner
Each flag needs a reviewer, evidence window, and allowed action. A cost signal may justify investigation. It should not, by itself, authorize deletion.
The goal isn’t just cost optimization. It’s strategic portfolio management — ensuring that what’s live in your cloud reflects the business priorities of your organization, not just the leftover results of past projects.
Once you’ve cleaned, categorized, aligned, and optimized your infrastructure, it’s time to ask a hard question: Where are we exposed — and how bad could it get?
Assess & mitigate risk
This step of IT portfolio management puts every resource, every project, every business-critical app under a magnifying glass — and asks: What’s vulnerable? What’s non-compliant? What’s quietly threatening uptime, security, or trust?
The theory is simple:
Risk = Likelihood × Impact.
Your job is to lower both — through visibility, automation, and strategic alignment.
But in complex environments, that means going beyond CVEs and security groups. You need to assess risk by context: lifecycle state, ownership, criticality, exposure, and drift from policy. And then build automated mitigation workflows that tie directly back to your portfolio management model.
How we do it in practice with Cloudaware CMDB:
- Surface vulnerable or misconfigured assets using filters & rules
→ Public-facing resources without encryption
→ “Operational” CIs with no owner or outdated lifecycle status
→ Assets failing CIS Benchmarks, PCI-DSS, or org-specific controls
→ Unused IAM roles with elevated privileges - Map risk across Virtual Applications and business services
→ Use related items and CI metadata to understand blast radius
→ Prioritize mitigation based on exposure vs. business value (e.g., is this a forgotten dev pod or a production payment API?)
→ Flag resources tied to high-priority projects or regulated environments - Feed risk signals into the portfolio
→ Tag risky CIs with severity levels
→ Link them to ongoing projects and initiatives in your project portfolio management workflows
→ Trigger workflows: notify owners, open remediation tickets, or auto-update CI status
The trap is severity without context. A public endpoint in an abandoned development account may share a finding with one attached to a payment service. Their business impact is different.
Prioritization improves when exposure, owner, service criticality, dependencies, and lifecycle state appear in the same review. If context is missing, mark the decision as low confidence. Enrich the record before the team automates a response.
But governance isn’t a finish line.
It’s that part of IT portfolio management that either becomes a living rhythm or quietly fades into background noise while shadow infra multiplies behind your back.
Read also: Choosing asset management software? These 15 Features Are a Must
Continuously govern & adapt
Governance usually fails quietly. The policy may still exist while the evidence behind it changes. Ownership can shift after a reorganization. New pipelines sometimes omit metadata. Services move to different platforms.
Treat those changes as portfolio events. They should reopen the affected ownership, lifecycle, cost, and risk decisions instead of waiting for the next annual review.
Here's how we make it stick:
1. Set governance boundaries that flex without breaking
Start by documenting actual rules — lifecycle triggers, tagging standards, cost center tags, owner attribution requirements, etc.
Not in a doc nobody reads. In logic your systems recognize.
Structure these policies so they adapt:
Set the evidence window and escalation path for these example rules using your environment baseline, service criticality, and retention policy.
- If a CI is marked “Operational” but has no observed activity within its configured evidence window, trigger a lifecycle review.
- If a container is spun up without owner tags or repo metadata, it’s non-compliant — flag it before it’s forgotten.
- If a resource’s region or cost center conflicts with the project’s config file, it’s a signal, not a failure — escalate accordingly.
2. Tie governance to change, not just audits
Lifecycle doesn't live in a spreadsheet. It flows through provision → change → retire, and it has to move with actual events.
That means:
- CI status updates tied to IaC changes, not Jira tickets
- Ownership reassignments triggered on team transitions
- Policy checks embedded into pre-deploy checks or GitHub Actions
- Real-time visibility into drift between actual state and expected state
This kind of continuous governance generates meaningful data — not just audit trails, but behavior patterns. It shows where project portfolio management efforts are misaligned with live infrastructure and where you need to re-sync.
3. Adapt your portfolio to reflect business evolution
This is where it gets strategic.
- When teams replatform from EC2 to EKS, are you retiring the right resources?
- When a business unit is sunset, do their services get flagged for decommission?
- When a new initiative is spun up, are the services, CIs, and budget lines reflected in the CMDB?
If not — you’re already drifting. And what looked like a clean portfolio last quarter? It’s out of sync with your organization.
Continuously Govern & Adapt isn’t glamorous. It’s config rules, tagging audits, Slack alerts, and tracking down lifecycle violators. But it’s what makes your IT portfolio management resilient.
So the next time you look at an EC2 tagged “Default,” you already know what process failed — and what happens next.
IT portfolio review scorecard
Portfolio reviews need their own health check. Track the measures below as trends and exception queues. Do not copy one universal target across the estate. A stable on-prem service and an ephemeral cloud workload age at different rates.
| Measure | How to calculate it | What it exposes |
|---|---|---|
| Owner coverage | Portfolio items with an approved accountable owner divided by in-scope items | Work that cannot be routed or approved |
| Service relationship coverage | CIs related to an application or business service divided by in-scope CIs | Assets with no usable business context |
| Lifecycle freshness | Items confirmed within the evidence window set for their class | Records that may no longer represent reality |
| Unallocated spend | Cloud and software spend with no accepted cost owner or service | Cost that cannot enter a portfolio decision |
| Risk context coverage | Findings linked to owner, service, criticality, and lifecycle evidence | Alerts that cannot be prioritized reliably |
| Retirement throughput | Approved retirements completed in the review period divided by approved retirements due | Decisions that are not reaching execution |
Review the exceptions behind each measure. A rising owner-coverage percentage can still hide a critical production service with no accountable team. Use the scorecard to find exceptions and the decision record to document the outcome.
The data stack behind a decision-ready IT portfolio
A portfolio view is only as current as the evidence feeding it. In a multi-cloud environment, that normally means discovery, billing, security, infrastructure-as-code, service mapping, and identity or ownership sources. The CMDB becomes useful when it reconciles those inputs into one reviewable record and keeps source and timestamp context.
1. Inventory and relationship model
Everything starts with a living, breathing CMDB. It’s the heartbeat of IT portfolio management — pulling in discovery data from AWS Config, Azure Resource Graph, GCP Asset Inventory, and Terraform state files.
Each Configuration Item (CI) is enriched with:
- CI type (
EC2,AKS,CloudSQL, etc.) - Tags:
owner,business_unit,project_id,lifecycle_state,compliance_status - Related items and logical associations
- Tied to actual business services and strategic initiatives
This builds your baseline of data — clean, contextual, and actionable.
2. Cost and allocation data
You can’t manage what you can’t quantify. Your stack needs cost attribution down to the CI level — rolled up by projects, business units, and service boundaries.
We’re talking:
- Budget thresholds based on
cost_centertags - Alerts for idle or over-provisioned resources
- Spend tracking aligned to project portfolio management plans
- Anomaly detection across clouds and services
Now your organizations aren’t just seeing numbers — they’re making decisions.
3. Policy and workflow signals
This is where policy enforcement becomes real. Ownership, encryption, tagging, lifecycle rules — these can’t live in PDFs. They need to live in GitHub Actions, Terraform validators, and deployment pipelines.
This layer includes:
- Tag validation at deploy
- Lifecycle state tracking tied to IaC
- Auto-alerts for drift, non-compliance, and data exposure
- Slack or Jira integrations to surface violations instantly
This makes policy decisions reviewable and routes violations to the team responsible for the next action.
4. Lifecycle evidence
Every CI should move through lifecycle states. Provisioned → Operational → Modified → Retire Pending → Retired isn’t a theory — it’s how you reflect truth in your portfolio.
Lifecycle transitions can be triggered by:
- IaC state changes
- CloudTrail events (e.g., termination)
- CI aging thresholds configured for the resource class
This keeps your data fresh, your workflows aligned, and your CMDB relevant to current business priorities.
5. Business context
This is what turns infra into insight.
You link CIs to:
- Applications
- Business services
- Strategic initiatives
- Active or archived projects
So when someone from leadership asks, “What infrastructure supports this initiative?” — you’ve got the full lineage. And when a project sunsets, your system can flag orphaned infra tied to that initiative, ready for retirement.
This is the crown jewel of portfolio management: Context + traceability + clean handoffs = true alignment across tech and the company.
This stack isn't just about control — it's about clarity. It turns chaos into context, costs into signals, and infrastructure into an asset that reflects how the business really runs.
Where Cloudaware fits
Cloudaware fits when operational reviews depend on inventory sources that change faster than spreadsheets or periodic exports. That includes resources across AWS, Azure, GCP, other clouds, and on-prem systems.
The Cloudaware CMDB combines multi-cloud and on-prem inventory with application and service relationships, ownership, cost, change, and compliance context. When a policy exception appears, a reviewer can trace the affected service, confirm the accountable owner, inspect dependencies, and route the next action from the same record.
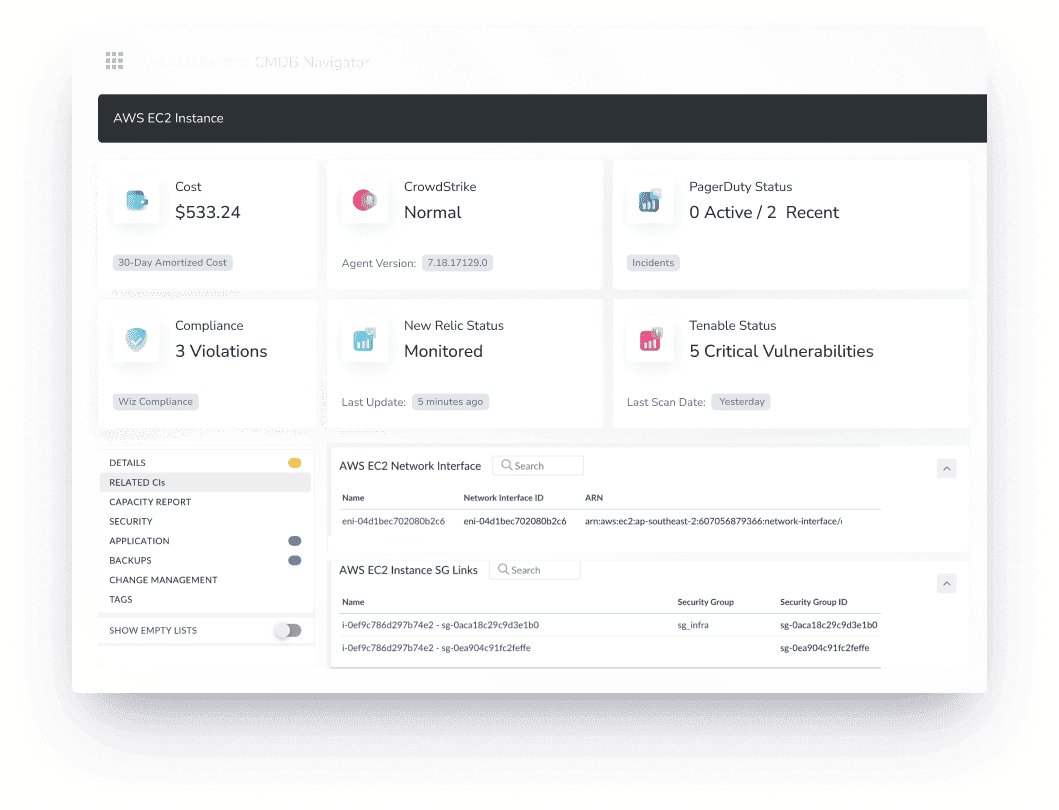
Portfolio governance still belongs to the team. It defines ownership rules, lifecycle states, review thresholds, source precedence, and approval paths. Cloudaware supplies the evidence layer and workflow surfaces those controls depend on.
For IT lifecycle tracking, use the evidence behind each state change to decide when an item needs review or can move to retirement.